Inside the GPU for LLM Inference
Last time we named the memory wall. This time we open the chip that creates it: SMs, warps, SIMT, HBM, tensor cores, low precision, and why NVLink beats the network long before you care about flops.
In the last article we got somewhere uncomfortable with two numbers alone.
Ops per second. Bytes per second.
From those we could already say: generating one token barely uses the arithmatic. Less than 1% of the wall clock is math. The other 99% is the chip waiting on weights from memory. Decode was not compute-bound. It was memory-bound by a factor that felt almost rude.
That piece was about what the bottleneck is.
This one is about the machine that creates it.
We are going to open a GPU and ask three questions:
- Why is it built so differently from the processor in your laptop?
- Why does moving a byte across it cost so much more than doing arithmetic on one?
- Once you see that, what can the hardware actually do to fight back?
It starts with a single bet about the kind of work this chip will spend its life doing.
Before the jargon piles up, here is a tiny map of the words we will need. Plain meanings first. Formal names after.
| Word you will hear | Plain meaning |
|---|---|
| Thread | One tiny worker doing the same program on its own data |
| Warp | A locked group of 32 threads that march together |
| SM | One "mini-GPU" tile; the chip is many of these stamped out |
| HBM | The big off-chip memory pool holding the model weights |
| Tensor core | Hardware that multiplies small matrices in one shot |
| SIMT | One instruction broadcast to many threads at once |
Keep that table nearby. Everything below is just that table with teeth.
The bet
The work this chip will do all day is the same few arithmetic operations, repeated across billions of numbers at once.
That is the shape of a matrix multiply (matmul): take a grid of numbers, multiply it by another grid, add. A transformer is mostly matmuls stacked with a little attention and nonlinearity between them.
Design a chip around that one assumption and it ends up looking nothing like the CPU in your laptop.
What a CPU is optimizing for
A CPU (central processing unit) is built to rush a single thread through as fast as it can, even when that thread keeps making unpredictable turns.
So most of its silicon does not go into arithmetic. It goes into anticipation:
- Prefetching: guess which memory you will need next and fetch early
- Speculation / branch prediction: guess which way an
ifwill go and start that path early - Out-of-order execution: rearrange independent instructions so the pipeline stays full
A chip built that way runs maybe a few tens of those fast threads at once. That is the right design for an OS, a compiler, a web server, a browser tab that keeps surprising you.
It is the wrong default for "multiply this giant matrix forever."
What a GPU is optimizing for
A GPU (graphics processing unit, though we now use it as a general accelerator) makes the opposite trade.
Take Nvidia's H100, the data-center chip I will use as the concrete example. Hopper is the architecture name for that generation (2022). Think of "Hopper" like a family name and "H100" like a specific model in that family.
It spends its silicon on 132 identical compute units, each holding up to 2048 threads at once. Over 270,000 threads in flight across the chip.
Not one of them is fast on its own. None gets the anticipation machinery a CPU lavashes on a single thread.
For this workload, that is exactly the right call. Even if your first reaction is that a chip full of slow threads just throws performance away.
When the job is the same operation over a billion elements, a hundred thousand slow threads in parallel beat a handful of fast ones by orders of magnitude.
Same goal. Different bet.
Same goal. Different bet.
Few fat speculative cores vs a grid of thin lockstep cores
Zoom into one SM
Those 132 compute units have a name: streaming multiprocessors, or SMs.
Plain meaning: an SM is one repeatable "tile" of the GPU. Registers, small fast memory, schedulers, CUDA cores, tensor cores. The whole chip is that tile stamped out again and again.
Understand one SM and you understand the GPU.
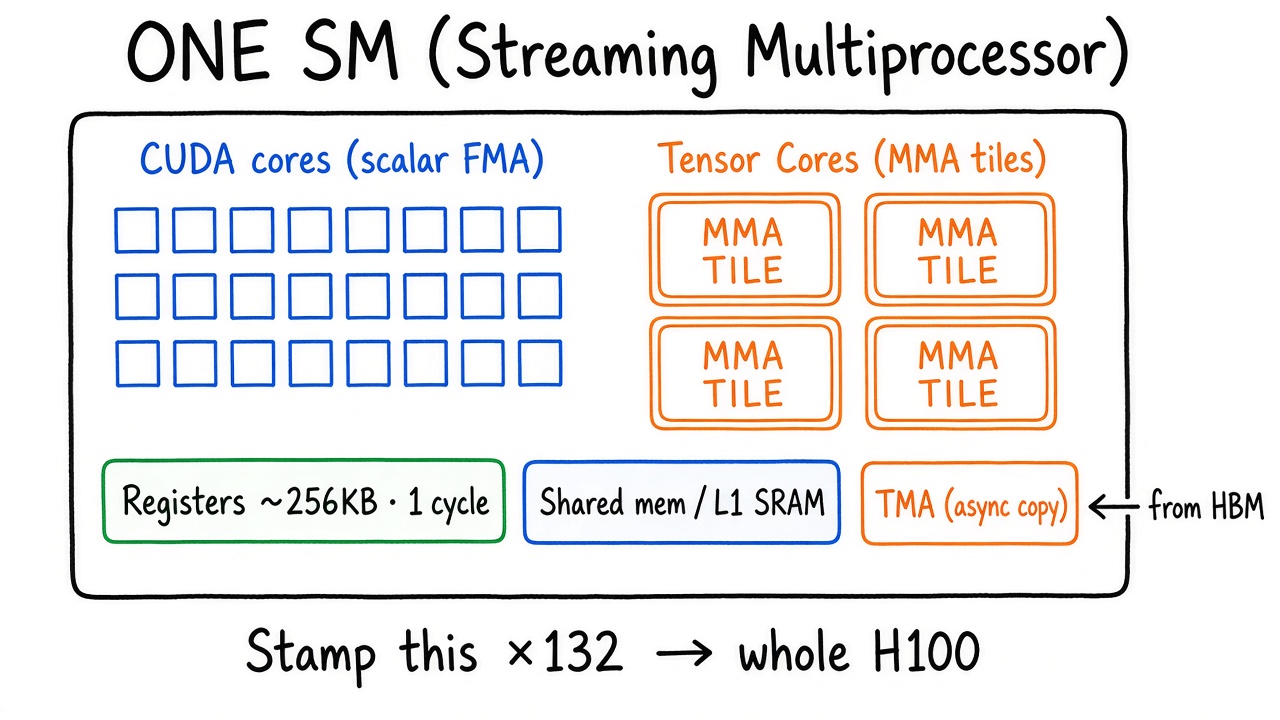
One SM design, stamped across the die
Understand one streaming multiprocessor · the H100 is ~132 of them
What sits inside one SM
The heart of an SM is its arithmetic units. Two kinds matter:
- CUDA cores: general-purpose scalar units. "Scalar" means one number at a time. Each does roughly one FMA (fused multiply-add:
a * b + c) per cycle. Good for bookkeeping, address math, random glue work. - Tensor cores: units that operate on whole matrix tiles, not single values. This is where the headline FLOPs live.
The H100's peak throughput, close to a thousand trillion operations a second (~1000 TFLOP/s, sometimes written as ~1 PFLOP/s depending on precision), comes almost entirely from those four tensor cores per SM, not the 128 CUDA cores beside them.
Everything else on the SM exists to keep those units fed. A math unit waiting on data is doing nothing.
Right against the cores sits the fastest memory on the chip:
- A register file (~256 KB): the absolute closest storage. Single-cycle access. Each thread's private working values live here.
- On-chip SRAM (~256 KB total budget per SM): part of this can be claimed as shared memory (a scratchpad the program manages by hand so cooperating threads can stage data they share). The rest behaves like L1 cache (hardware-managed, automatic).
Four schedulers keep it moving. Each picks a ready group of threads every cycle and issues their next instruction.
Hopper also added a dedicated unit called the Tensor Memory Accelerator (TMA). Plain meaning: a little copy engine whose only job is to stream blocks of data from main memory into that SRAM in the background, so worker threads do not spend their own instructions babysitting the transfer.
One SM: up to 2048 threads. Across 132 SMs: that is where the ~270k number comes from.
One SM: keep the math units fed
CUDA cores tick · tensor cores glow · TMA streams weights in
How programmers name the work
Hardware thinks in warps. Software launches work with a slightly different vocabulary. It helps to see the stack once:
How work is named on a GPU
Thread → warp (32) → thread block → grid · hardware schedules warps
| Term | What it is |
|---|---|
| Thread | One lane executing the program |
| Warp | 32 threads in lockstep (hardware schedule unit) |
| Thread block (CTA) | A bundle of threads that share one SM and its shared memory |
| Grid | All the blocks launched for one kernel |
You write blocks. The silicon schedules warps. That mismatch is where a lot of "why is my kernel slow" debugging lives.
Warps: the real unit of work
Those groups of threads have a name. Warps.
A warp is 32 threads, and it is the real unit the hardware schedules. The 2048 threads on an SM always move in warps of 32. Never one at a time.
What defines a warp is this: all 32 threads execute the same instruction at the same moment, each on its own data.
The hardware fetches that instruction once, decodes it once, and fires it across all 32 lanes in lockstep. Nvidia calls this SIMT: Single Instruction, Multiple Threads.
SIMT vs SIMD (people mix these up)
You may already know SIMD from CPUs: Single Instruction, Multiple Data. AVX, NEON. One instruction hits a wide vector register.
SIMT is a cousin, not a twin:
- SIMD widens one instruction across lanes inside a vector register
- SIMT broadcasts one instruction across many threads, each with its own registers and program counter state, and some lanes can be masked off
That masking ability is why warp divergence exists as a concept. AVX does not really "take an if-branch per lane" the same way.
SIMD vs SIMT (close cousins, not twins)
SIMD: one instruction, wide vector · SIMT: one instruction, many threads that can mask off
That single SIMT fact is where a lot of the GPU's compute density comes from.
Fetching and decoding an instruction costs real silicon and energy. A scalar processor pays that cost for every operation. A GPU pays it once per warp and spreads it across 32. The control overhead nearly dissapears, which frees the chip to put silicon into arithmetic instead.
The SM's four schedulers work at this same granularity. Each issues one ready warp per cycle. With up to 64 warps resident at once, they almost always have one ready to fire.
That "how many warps can live on the SM at once" idea has a name: occupancy. Higher occupancy usually means better latency hiding, until you run out of registers or shared memory.
Occupancy: how full is the SM?
More resident warps → better latency hiding · limited by registers and shared memory
A warp: 32 lanes, one instruction
Fetch once · decode once · fire across all lanes in lockstep
The weakness sitting inside the strength
That lockstep is also SIMT's weakness.
A warp shares one instruction stream across all 32 threads. So it can only do one thing at a time.
What happens when the threads need to do different things?
Say the code hits an if / else, and inside one warp some threads take the if while the rest take the else. There is only one instruction stream. The hardware cannot run both branches at once.
It runs them back to back:
- the
ifpath first, with theelsethreads masked off (present, but idle) - then the
elsepath, with theifthreads masked
Each thread sits idle through the half it skipped.
So a balanced if / else costs you both paths in sequence and cuts throughput roughly in half. Nesting branches only compounds it.
This is warp divergence. One of the two cardinal sins of GPU programming.
Warp divergence: both paths, back to back
If threads take if · then else · each idles through the half it skipped
The other is about memory, not control flow. We will get there.
The memory ladder
We keep saying the math is fast and the data is slow.
The reason is physical.
The GPU's memory is a ladder of four levels. Each step away from the compute units trades speed for capacity.
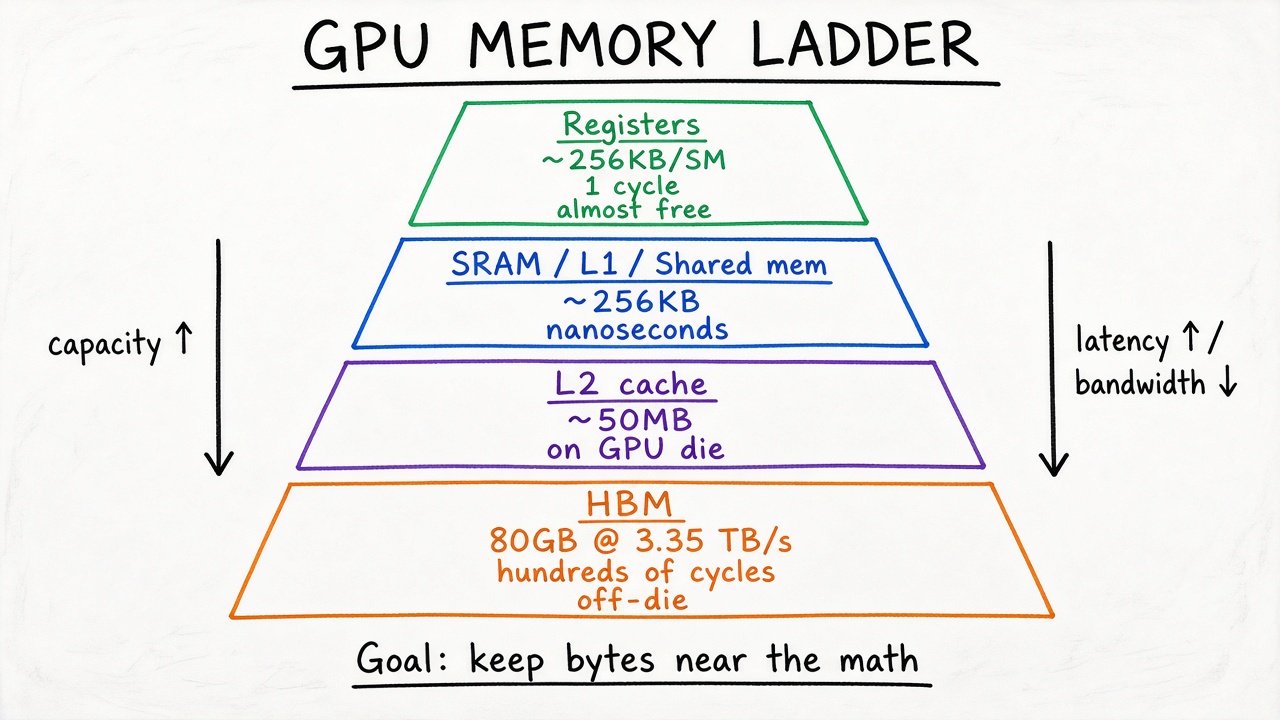
Memory is a ladder
Capacity climbs · speed falls · HBM is the expensive basement
| Level | Rough size (H100-class) | Feel |
|---|---|---|
| Registers | ~256 KB / SM | 1 cycle. Almost free. |
| SRAM / L1 / shared mem | ~256 KB / SM | Nanoseconds. Still on the SM. |
| L2 cache | ~50 MB | Still on the GPU die. Shared by all SMs. |
| HBM | 80 GB @ 3.35 TB/s | Off the compute die. Hundreds of cycles to return. |
HBM means High Bandwidth Memory: stacks of DRAM sitting beside the GPU die, connected by a very wide bus. "High bandwidth" is relative to older GDDR-style setups. Relative to the tensor cores, it is still the slow basement.
Top to bottom: roughly a hundredfold drop in bandwidth and a thousandfold jump in latency.
Reaching down to HBM for a byte costs vastly more than doing arithmetic on a byte you already have up top.
That asymmetry is the whole game.
GPU programming is mostly about staging data up this ladder and keeping the tensor cores fed from the fast end.
How the GPU survives a stall
So a trip to HBM costs hundreds of cycles.
A CPU would dodge a wait like that by guessing what comes next and fetching early (prefetch).
The GPU does almost none of that.
How does it survive?
It does not avoid the stall. It hides it.
An SM keeps up to 64 warps resident at once. When one warp fires a load to HBM and stalls, a scheduler just runs another warp that is ready. By the time the first warp's data comes back, dozens of others have taken their turn.
This works becuase switching warps is free.
Every resident warp's registers stay in the register file the whole time. There is nothing to save or restore (no context-switch tax). The scheduler just points at a different warp next cycle.
A CPU burns real cycles to swap threads. An SM pays nothing.
That is latency hiding. The GPU's whole answer to slow memory.
Latency hiding: stall one warp, run another
Warp A waits on HBM · scheduler keeps firing ready warps · switch is free
Each warp still waits hundreds of cycles for HBM. The SM, with enough warps in flight, never looks like it is waiting.
If occupancy is too low, latency hiding fails. The stall becomes visible wall-clock time. That is why "my kernel uses too many registers per thread" can destroy performance even when the math looks fine.
The second sin: uncoalesced access
Here is the other cardinal sin. And this one wastes the HBM bandwidth the whole chip is starved for.
It starts with one limitation: the hardware cannot fetch a single lonely value from HBM. It moves a whole cache line (a fixed-size block of neighboring bytes) at a time.
So when the 32 threads in a warp want values that sit next to each other, they fall inside the same block, and one transaction serves the entire warp.
That is coalesced access. The efficient case. Every byte moved is a byte some thread wanted.
Now scatter those 32 addresses across memory.
Each thread's value lands in a different block. The hardware runs a seperate fetch for each. Up to 32 transactions where the coalesced version needed one. And every block it drags in is mostly bytes nobody asked for, hauled across the bus, and thrown away.
The arithmetic is identical either way.
The only thing that changed is where the data sits in memory, and it can cost many times the bandwidth.
On a chip this memory-bound, data layout is as decisive as the math.
Coalesced vs scattered
Neighbors = one cache-line trip · scatter = up to 32 trips of mostly waste
Two sins, one sentence each:
- Divergence wastes compute (lanes idle on the wrong branch).
- Uncoalesced access wastes bandwidth (bus hauls junk).
The memory wall shows up in the product line
Latency hiding. Coalescing. The whole obsession with feeding the compute units. It all traces back to one trend with a name: the memory wall.
Across GPU generations, the compute side keeps pulling away from the memory side.
Bandwidth has grown steadily: roughly 2 TB/s on the 2020 A100 (Ampere) to about 8 TB/s on the 2024 B200 (Blackwell). A fourfold gain in four years.
Peak compute climbed faster still, largely becuase each generation added a lower-precision math format that multiplies throughput.
The two curves keep diverging. That widening gap is the wall.
The memory wall, as growing curves
Compute races ahead · bandwidth lags · the gap is the story
Nvidia basically ran the experiment for us
The H200 uses the exact same compute die as the H100. Same tensor cores. Same peak FLOPs.
The only thing they changed is the memory: 141 GB of faster HBM3e at 4.8 TB/s, up from the H100's 80 GB of HBM3 at 3.35.
For memory-bound work, which is most LLM decode at the batch a single request sees, that upgrade alone is a genuine speedup.
Same compute die. Different memory.
H200 keeps the tensor cores · upgrades HBM · decode feels it
Direct evidence that inference is limited by bandwidth, not by how fast the tensor cores can multiply.
Every new generation, Nvidia attacks this wall the same few ways:
- Lower precision, so each weight moves fewer bytes
- Faster HBM
- Wider links between chips
Whether a given operation is stuck against the wall or limited by raw compute still comes down to one number: arithmetic intensity (ops performed per byte moved), and the roofline we walked last time.
Roofline: where prefill and decode sit
Decode stays under the slanted roof · prefill climbs toward the flat compute roof
Before we leave the hardware, it all comes back to that ridge.
The ~295 ops/byte that seperates memory-bound from compute-bound on the H100 is not a free-standing number. It is these two hardware peaks divided:
Where the ridge number comes from
Peak ops/s ÷ peak bytes/s = ops/byte that separates the two roofs
Tensor cores are the compute roof. HBM is the bandwidth roof. The ridge is where they meet.
Everything we said about why decode lands deep on the memory-bound side and prefill lands on the compute side comes back to those two ceilings.
Tensor cores: why four small units own the chip
Earlier I said we would come back to tensor cores.
A CUDA core is scalar. It multiplies two numbers and adds a third. One result per cycle. That FMA is the basic "do math on one value" brick.
A tensor core does not deal in single numbers.
In one instruction it multiplies two small matrices and adds a third, producing a whole tile of results at once, where a CUDA core would grind through them one at a time.
That operation is matrix multiply-accumulate (MMA). And it is basically all a tensor core does.
That narrowness is the point.
A transformer spends well over 90% of its arithmetic inside matrix multiplies. So a unit that does nothing else, very fast, is the highest-leverage silicon Nvidia can build.
The H100 has 528 of them (four per SM). They produce the overwhelming majority of its peak throughput.
One caveat: that peak is theoretical. Cores perfectly fed. Sustained throughput in real kernels typically reaches 50 to 80% of peak for well-tuned code, and considerably less for unoptimized implementations.
Marketing peak ≠ what your kernel actually sustains.
CUDA core vs Tensor Core
One scalar FMA per cycle · vs one MMA tile in a single instruction
Lower precision pays twice
There is a second lever built into the hardware rather than the kernel: run these cores at lower precision.
"Precision" here means how many bits you use to store each number.
Lower precision pays off twice:
- Storing a number in fewer bits lets the tensor cores push more of them through each second
- It leaves fewer bytes to haul across the memory bus
More compute and less memory traffic from the same silicon.
So every tensor-core generation has added a lower-precision format:
| Generation | Roughly when | New low-precision bet |
|---|---|---|
| Volta (V100 era) | 2017 | 16-bit floats |
| Hopper (H100) | 2022 | 8-bit (FP8) |
| Blackwell (B200) | 2024 | 4-bit (FP4) |
Each having of the bits roughly doubles the throughput.
Lower precision pays twice
Fewer bits → more ops/sec → fewer bytes on the bus
Why a model can tolerate this
A floating-point number splits into three fields:
- Sign bit
- Exponent: how large or small the number can be (range)
- Mantissa (also called significand): the fine detail (precision)
Deep learning leans on range while staying forgiving about fine precision.
BF16 (bfloat16) is the clean example. It keeps all eight of FP32's exponent bits, so the range is identical, and cuts the mantissa from 23 bits down to seven. Training barely notices.
What a float actually stores
Sign · exponent (range) · mantissa (fine detail) · BF16 keeps FP32 range
And there is a safeguard: the multiplies run in low precision, but the results often accumulate back in FP32, so errors do not pile up as fast as you fear.
One caution on the marketing.
When Nvidia headlines a 9× speedup, that blends the precision gain with faster interconnects and ideal benchmarks. The honest per-generation gain on real work is more like 2× to 4×.
Be honest about the fence.
One GPU is not enough
A frontier model does not fit on one GPU. Its weights run to hundreds of gigabytes, well past the 80 or 140 a single chip holds.
So the model gets split across many GPUs that then have to talk constantly.
How fast they can talk is the next constraint.
Scale-up vs scale-out
There are two ways to wire them togheter.
Scale-up packs many GPUs into one box or rack joined by NVLink, Nvidia's dedicated GPU-to-GPU link, and a crossbar called NVSwitch that lets every GPU reach every other at full speed. Plain meaning: a private high-speed neighborhood for GPUs.
NVLink is fast and keeps getting faster:
- ~600 GB/s per GPU on the A100
- ~900 GB/s on the H100
- ~1.8 TB/s on Blackwell
Scale-out is the other way. Seperate boxes linked by ordinary data-center networking. InfiniBand (or Ethernet) at a few hundred gigabits a second. Roughly an order of magnitude slower per byte.
Why does that gap matter?
Tensor parallelism splits each layer's matrix multiply across GPUs, so they have to exchange partial results at every layer. Dozens of times per token. Techniques like all-reduce / all-gather show up here: every GPU needs a piece of everyone else's answer.
Tensor parallelism needs a fast fabric
Split one matmul across GPUs · exchange partials every layer · NVLink makes that cheap
Inside an NVLink domain, that is cheap.
Across InfiniBand, it is the bottleneck.
So Nvidia keeps growing the fast domain.
A DGX box held eight GPUs on both the A100 and H100 generations. The Blackwell GB200 NVL72 puts 72 GPUs in one liquid-cooled rack, all in a single NVLink domain. Far more of the model fits in the fast neighborhood before you are forced out onto the slow fabric.
Scale-up vs scale-out
NVLink domain feels free for tensor parallel · InfiniBand is the slow exit
same rack / NVLink domain     =  cheap collectives, tensor parallel feels free
across InfiniBand / Ethernet  =  the fabric becomes the new memory wall
And it is not only Nvidia
It is easy to come away thinking this story is only about Nvidia.
It is not.
The physics we covered, the memory wall, the value of low precision, scaling up before scaling out, applies to anyone building these chips. And there are real alternatives.
Google's TPU (Tensor Processing Unit) throws out the SM model entirely and builds the chip around one giant systolic array: a fixed grid of multiply-accumulate cells that data flows through rythmically, with no trips back to a register file in between. Well suited to dense matrix multiply. Not much else. Rentable for now mostly on Google Cloud.
AMD's MI300X is closer to a GPU. On paper it beats the H100 where it matters here: 192 GB of HBM, more than double. A model that needs two H100s can fit on one.
And yet most teams still reach for Nvidia.
The deciding factor is usually software.
CUDA (Compute Unified Device Architecture) has had almost two decades to build up the libraries and tooling that all of AI now sits on. ROCm, AMD's equivalent stack, is still catching up.
For most teams, that maturity is the real binding constraint.
Same physics. Different software gravity.
TPU systolic flow · AMD more HBM · CUDA still wins most teams
Which is also a good place to stop.
We spent this article on the machine. The next one should be about the kernels: the code that makes the machine fast. FlashAttention-shaped work, quantization in practice, continuous batching, the things that attack the bus bill from software instead of silicon.
Glossary (for when a word comes back)
| Term | One-line meaning |
|---|---|
| ALU / CUDA core | Scalar math lane; one FMA-ish op at a time |
| Tensor core | Matrix-tile math unit; MMA in one instruction |
| FMA | Fused multiply-add: a*b + c |
| MMA | Matrix multiply-accumulate on a tile |
| SM | Streaming multiprocessor; one repeatable GPU tile |
| Warp | 32 threads in lockstep |
| SIMT | Single instruction, multiple threads |
| SIMD | Single instruction, multiple data (CPU vector style) |
| Occupancy | How many warps can live on an SM at once |
| Shared memory | Programmer-managed scratchpad on the SM |
| HBM | High Bandwidth Memory; big off-die weight pool |
| TMA | Async copy engine from HBM into SM memory |
| Coalesced access | Warp touches neighboring addresses; one bus trip |
| Warp divergence | Warp takes both sides of a branch back-to-back |
| Latency hiding | Run other warps while one waits on memory |
| Arithmetic intensity | Ops per byte moved |
| Roofline ridge | Intensity where compute roof meets bandwidth roof |
| NVLink / NVSwitch | Fast GPU-to-GPU fabric inside a scale-up domain |
| Tensor parallelism | Split one layer's math across GPUs |
Things to hold onto
- CPU and GPU are different bets. Few fat speculative cores vs many thin lockstep cores.
- The SM is the unit. Stamp it out 132 times and you have an H100-class chip.
- Warps of 32 are what the hardware actually schedules. SIMT buys density. Divergence taxes it.
- Memory is a ladder. Registers → SRAM → L2 → HBM. Capacity up. Speed down. Hard.
- Latency hiding, not prefetch magic, is how GPUs survive HBM stalls: keep enough warps resident that someone is always ready.
- Coalesced access is not a style tip. On a memory-bound chip it is whether you waste the bus.
- H200 vs H100 is the clean natural experiment: same compute die, faster memory, real decode speedup.
- Tensor cores exist becuase transformers are >90% matmul. MMA tiles beat scalar CUDA cores for this job.
- Lower precision pays twice: more ops/sec and fewer bytes on the bus.
- Scale-up before scale-out. NVLink domains are the fast neighborhood. InfiniBand is the slow fabric you leave for later.
- CUDA maturity often beats a better HBM datasheet.
One sentence:
The GPU is not "a fast CPU with more cores." It is a machine designed around one bet, matrix multiplies forever, and almost every ugly detail of LLM inference is just that bet colliding with the memory wall.
The rabbit hole continues.